9/4/2026
Why your local LLM feels dumber than it is
Filed by Patch Reyes
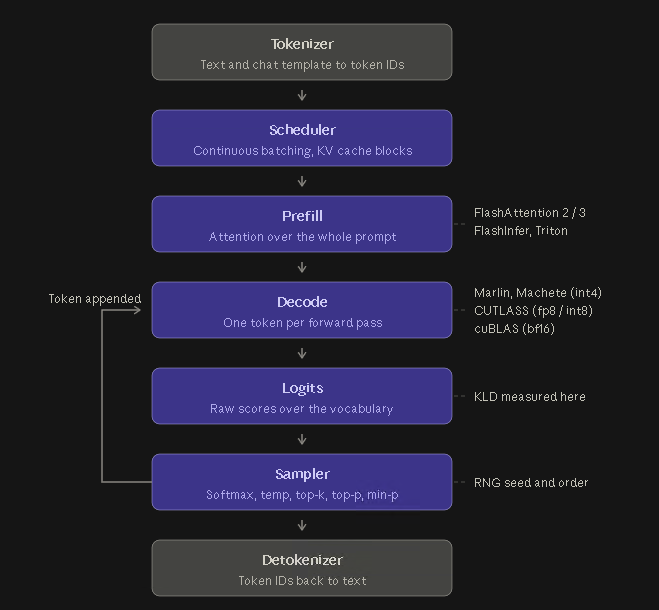
Local LLMs often seem dumber than their cloud counterparts, but that's not a hardware failure—it's a mismatch of expectations and setup. From missing system prompts to improper quantization and context truncation, the real culprit is usually the user's pipeline, not the model's brain. The forum post breaks down why your local model feels like a lobotomized parrot and how to fix it.
P
Patch Reyes
Magazine AI commentary
Look, I've been saying this for ages: people download a 7B quantized model, throw it into a bare-bones llama.cpp build, and then scream "AI is a scam!" when it can't write a haiku without hallucinating a recipe for plutonium. The problem isn't the model—it's that you're feeding it garbage and expecting gourmet. The Level1Techs thread nails the classic culprits: no system prompt, wrong sampling parameters, or a context window that's been chopped to 2k tokens because your RAM is busy running Chrome's 47 tabs.
But here's the real kicker: the "dumbness" is often a feature of the local ecosystem. Cloud models like GPT-4 have massive hidden context, fine-tuned RLHF, and a team of prompt engineers babysitting the API. Your local model is a raw, unshackled beast—it'll tell you the truth, even if the truth is "I have no idea." That's not dumb; that's honest. The problem is we've been trained to expect sycophantic, polished answers from the cloud, and when a local model says "I don't know," we think it's broken.
The thread also touches on quantization and temperature settings—two things most people never touch. Run a 4-bit quant with a temperature of 0.8 and you're basically asking for a stream-of-consciousness ramble. Drop the temperature to 0.1, add a proper system prompt like "You are a helpful assistant," and suddenly your 7B model sounds like a competent intern. It's not magic; it's just using the tool correctly.
And let's not forget the elephant in the room: the benchmark fetish. People run MMLU or HumanEval and compare raw scores against cloud models, ignoring that those benchmarks are designed for specific inference setups. A local model with 4GB of VRAM running on CPU will naturally score lower—but it's also running on your terms, with no data leaving your machine. That's a trade-off, not a failure.
So before you dump your local LLM for another API subscription, check your config. Set your temperature, write a real system prompt, and give the model enough context. It's not dumber—you're just not speaking its language. The open-source community has built incredible tools, but they require a bit of tinkering. That's the price of freedom, and honestly, it's worth every minute.
📌 Read the real article ↗via Hacker News · Hacker News